










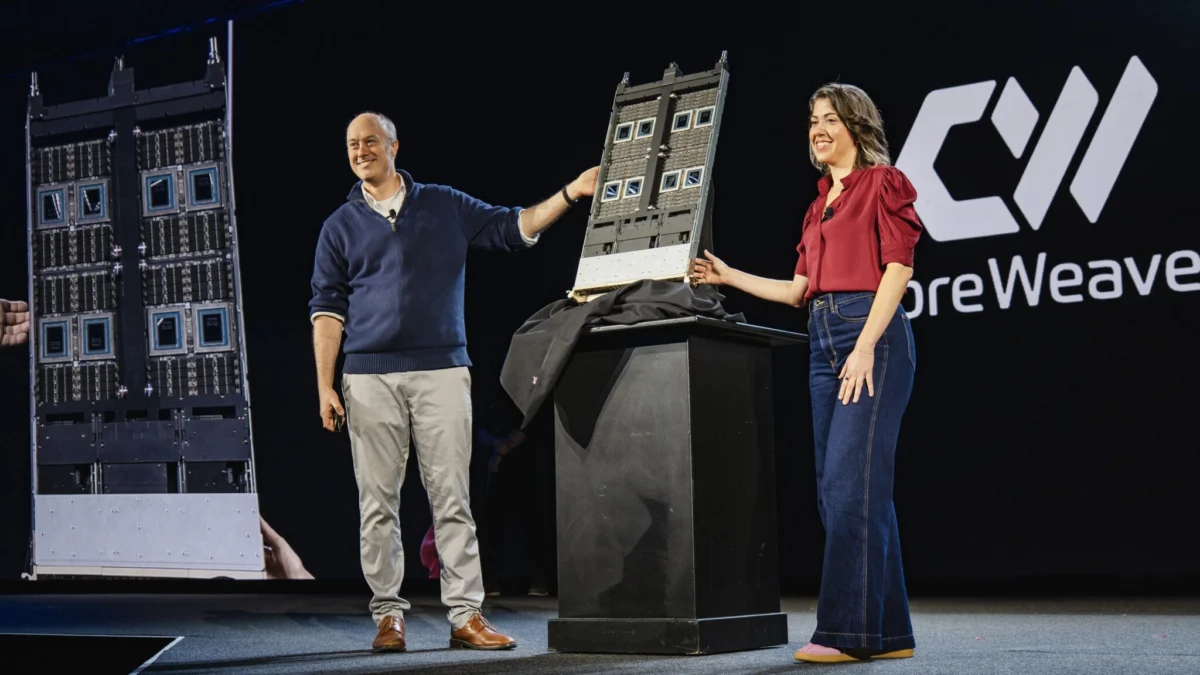
SAN FRANCISCO — In a milestone announcement at the CoreWeave Fully Connected conference in San Francisco, specialized cloud provider CoreWeave and computing titan NVIDIA have unveiled their next-generation AI infrastructure, headlined by the commercial debut of the NVIDIA Vera Rubin NVL72 systems. Building upon nearly a decade of deep co-engineering—dating back to the legacy Volta generation—the partnership continues to push the boundaries of accelerated computing.
The centerpiece of this release is the deployment of NVIDIA Vera Rubin NVL72 hardware paired with Spectrum-X 102.4T Ethernet networking directly into CoreWeave Cloud. Applied AI lab Cognition, famous for developing the groundbreaking Devin AI software engineer, has officially become the first customer to run production workloads on the Vera Rubin architecture. Alongside this hardware leap, CoreWeave introduced the NVIDIA Vera CPU—the industry’s first CPU purpose-built for AI agents—and CoreWeave Forge, an integrated environment designed to bridge the gap between AI model training, evaluation, and production deployment.
1. Main Facts
The latest announcements from CoreWeave Fully Connected underscore a paradigm shift in how enterprise-grade AI infrastructure is conceptualized, deployed, and monetized:
- Vera Rubin NVL72 Availability: CoreWeave is among the world’s first cloud providers to deliver NVIDIA Vera Rubin NVL72 systems into production hands. The system leverages Spectrum-X 102.4T Ethernet networking to achieve unprecedented speeds.
- Cognition as First Adopter: Cognition is utilizing the new architecture for training, reinforcement learning, and production inference for Devin, experiencing a massive performance uplift.
- NVIDIA Vera CPU: Tailored specifically for agentic AI workflows, the Vera CPU packs 128 CPUs and 11,264 cores into a single rack, enabling more than 11,000 concurrent, hardware-isolated agent environments.
- CoreWeave Forge Launch: Forge unifies model training, continuous evaluation, and post-processing tools—such as integration with Weights & Biases, OpenPipe, and the open-source marimo notebook project—into a single connected pipeline. Early enterprise adopters include Canva, Capital One, and MasterClass.
- Cross-Sector Adoption: Beyond tech startups, healthcare providers like Ennoble Care are leveraging CoreWeave’s infrastructure to run clinical AI inference at scale, utilizing reserved NVIDIA RTX PRO 6000 GPU capacity.
2. Chronology of a Decade-Long Partnership
To fully appreciate the significance of the Vera Rubin rollout, industry analysts point to the sustained, multi-generational trajectory of the CoreWeave and NVIDIA collaboration.
- 2015–2016 (The Volta Genesis): CoreWeave adopts NVIDIA V100 GPUs. In a testament to the longevity of the NVIDIA platform, these legacy V100 units continue to successfully execute customer workloads nearly a decade after their initial launch.
- Early 2024 (Scaling for Foundation Models): Cognition scales its infrastructure on CoreWeave to thousands of GPUs in just nine months, laying the computational foundation necessary to train and operate Devin, the world’s first fully autonomous AI software engineer.
- Early 2025 (The Blackwell Era): CoreWeave achieves record-breaking benchmarks, consistently dominating MLPerf training and inference rounds while securing Platinum rankings across SemiAnalysis ClusterMAX 1.0, 2.0, and 3.0 evaluations.
- Mid-2025 (The Vera Rubin Arrival): CoreWeave takes delivery of its initial Vera Rubin NVL72 production racks. Within days, CoreWeave’s engineering team—working in lockstep with NVIDIA—stands up a fully operational production cluster for Cognition.
- The Present (Fully Connected Event): CoreWeave officially opens Vera Rubin NVL72 to early-access customers, simultaneously unveiling the Vera CPU and the CoreWeave Forge ecosystem at the San Francisco conference.
3. Supporting Data and Performance Metrics
The architectural improvements of the Vera Rubin system and Vera CPU translate directly into measurable economic and computational efficiencies. In computing environments where the cost per generated token dictates operational feasibility, these metrics are transformative:
- 4.8x Token Throughput Increase: In early benchmarking against a GB200 NVL72 baseline using real-world software engineering tasks sampled from FrontierCode, Cognition observed up to a 4.8-fold increase in total token throughput for SWE-2 inference workloads on the Vera Rubin NVL72.
- 3x Faster Sandbox Startups: Agentic AI workloads require massive parallel environments for post–training reinforcement learning. CoreWeave’s deployment of the NVIDIA Vera CPU yielded greater than 3x faster agent sandbox startup times.
- 1.7x Terminal-Bench Performance Gains: Across all passing tasks on Terminal-Bench, the Vera CPU demonstrated a 1.7x performance multiplier.
- Massive Concurrency: A single rack equipped with NVIDIA Vera CPUs supports more than 11,000 concurrent, hardware-isolated environments (allocated at one core each), reinforced by BlueField-4 DPUs and Spectrum-X Ethernet switches to guarantee low-latency, secure communication.
4. Official Responses and Industry Perspectives
Leadership from both NVIDIA and CoreWeave, alongside key enterprise partners, emphasized the holistic nature of the platform stack during the San Francisco announcements.
Ian Buck, Vice President of Hyperscale and High-Performance Computing at NVIDIA, highlighted the enduring economic value of the companies’ joint architecture:
"NVIDIA accelerated computing delivers value across generations. CoreWeave’s NVIDIA V100 GPUs are still running customer workloads nearly a decade after Volta launched, even as CoreWeave brings Vera Rubin NVL72 into production. That’s the strength of the NVIDIA platform: infrastructure that keeps earning for years, and the flexibility to put the right GPU on the right workload."
Silas Alberti, representing the founding team at Cognition, underscored the operational necessity of tightly integrated hardware and software ecosystems:
"Agentic coding is a complex workload: long contexts, high concurrency, and token volumes where cost per token decides what we can ship. Having all of it on one platform, with NVIDIA and CoreWeave engineers who work the hard problems alongside ours, matters more to us than any single spec."
5. Broader Implications for the AI Landscape
The simultaneous launch of Vera Rubin, the Vera CPU, and CoreWeave Forge addresses several critical bottlenecks that have historically plagued enterprise AI adoption.
Bridging the Training-Inference Divide
Historically, the loop governing AI evolution—where production behavior feeds back into training runs, and evaluations sharpen subsequent model versions—has been fragmented across multiple disparate vendor tools. This fragmentation frequently results in signal degradation at every handoff. CoreWeave Forge solves this by establishing a unified environment. Furthermore, the integration of NVIDIA Dynamo powers CoreWeave’s managed inference service alongside RL Rollouts (currently in private preview), allowing live deployments to ingest new model checkpoints dynamically without requiring disruptive system redeployments.
Powering the Rise of Autonomous AI Agents
As generative AI transitions from static chat interfaces to dynamic "agentic" workflows—systems capable of reasoning, executing code, using tools, and running multi-step problem solving—the demands on underlying cloud infrastructure have fundamentally changed. Agents require massive concurrency for reinforcement learning environments alongside ultra-low-latency inference to maintain real-time responsiveness.
By combining the raw compute power of Vera Rubin NVL72 with the high-density virtualization capabilities of the Vera CPU and CoreWeave Sandboxes, the platform removes the physical scaling limits that previously constrained autonomous agent development.
Enterprise Real-World Deployment
The impact of this infrastructure extends far beyond Silicon Valley tech labs. For instance, Ennoble Care—a home-based healthcare provider managing approximately 50,000 high-need Medicare patients across 15 states—has selected CoreWeave to execute clinical AI inference. By harnessing reserved NVIDIA RTX PRO 6000 GPU capacity via the CoreWeave Kubernetes Service, Ennoble Care is scaling specialized AI agents designed to streamline clinical documentation, provide real-time clinical decision support, and automate burdensome back-office administrative workflows.
Conclusion
With nine of the top ten leading AI labs already relying on its infrastructure, CoreWeave’s rapid integration of NVIDIA’s Vera Rubin platform solidifies its standing as a premier cloud provider for next-generation intelligence. By delivering hardware designed specifically for the unique pressures of agentic workflows and unifying the post-training feedback loop through Forge, CoreWeave and NVIDIA are actively transforming experimental AI models into dependable, revenue-generating production systems.



