











The traditional machine learning pipeline has, for over a decade, followed a rigid, well-defined sequence: collect massive datasets, painstakingly clean raw text, perform feature engineering—often using techniques like TF-IDF or word embeddings—and finally, train a specialized classifier such as a Logistic Regression or Random Forest model. For data scientists, this was the "standard drill." It […]
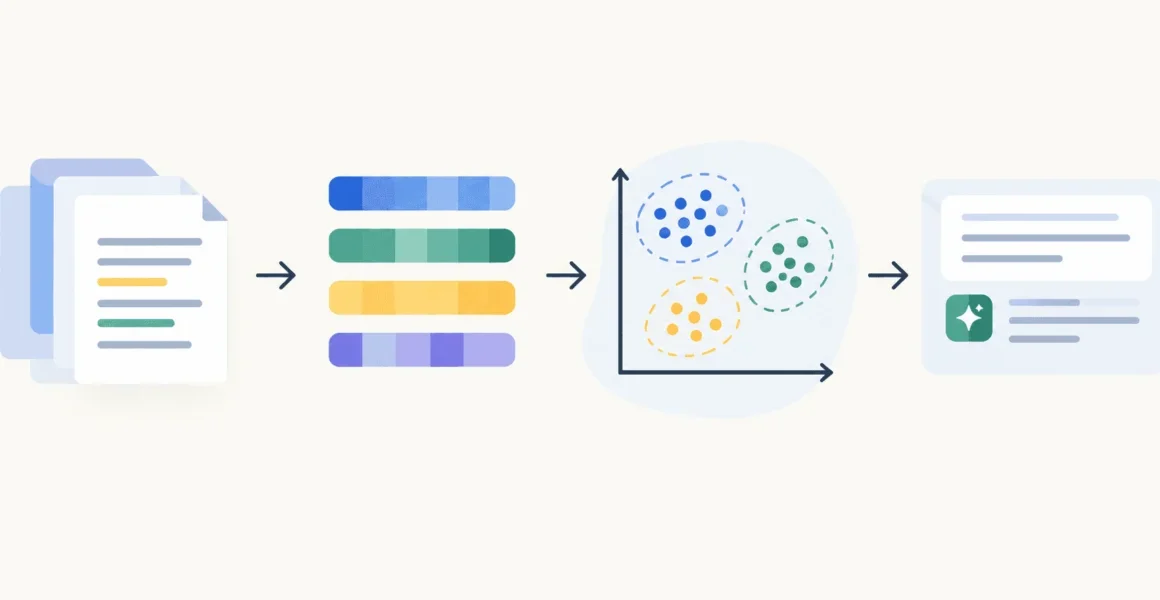
Democratizing AI: Building a Lightweight, High-Performance RAG Pipeline with Scikit-Learn
In the rapidly evolving landscape of Artificial Intelligence, Retrieval Augmented Generation (RAG) has emerged as the gold standard for grounding Large Language Models (LLMs) in factual, domain-specific data. However, the prevailing narrative suggests that deploying a RAG system requires a massive architectural investment: expensive, managed vector databases, complex orchestration frameworks, and high-latency API calls to […]