










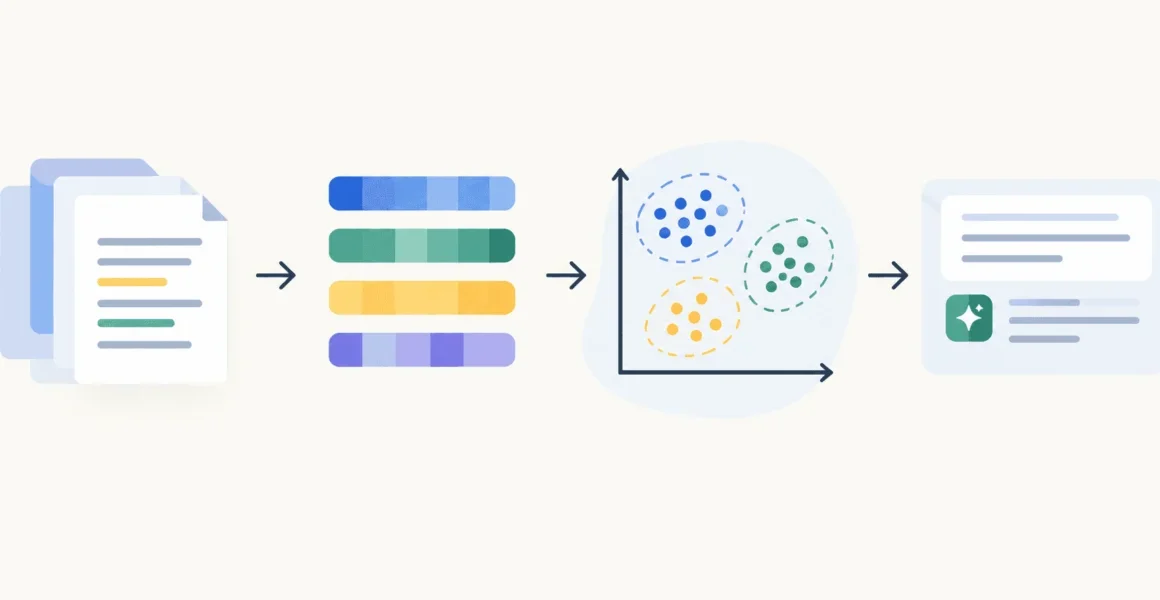
In the rapidly evolving landscape of Artificial Intelligence, Retrieval Augmented Generation (RAG) has emerged as the gold standard for grounding Large Language Models (LLMs) in factual, domain-specific data. However, the prevailing narrative suggests that deploying a RAG system requires a massive architectural investment: expensive, managed vector databases, complex orchestration frameworks, and high-latency API calls to […]
Headline
Tag: learn
Back To Top