









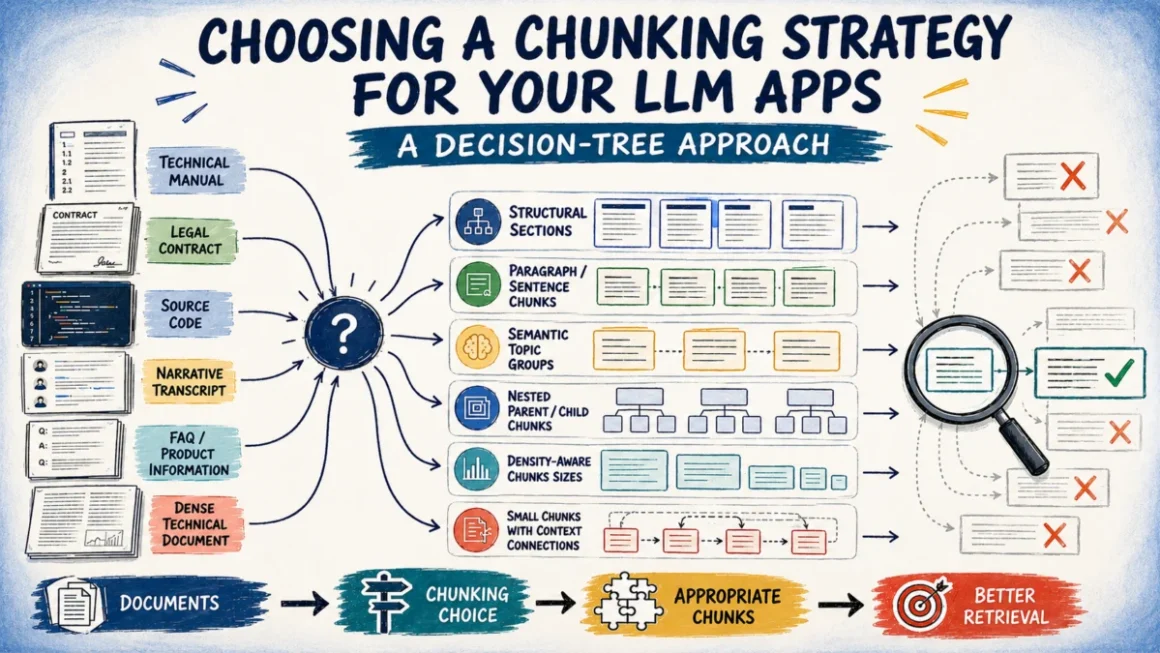
In the rapidly evolving landscape of Retrieval-Augmented Generation (RAG), the efficacy of your AI system is rarely determined solely by the sophistication of your Large Language Model (LLM). Instead, it is frequently decided long before the prompt is ever sent, during the data preprocessing phase. Specifically, the "chunking strategy"—the method by which you partition large […]
Headline

Tag: chunking
Back To Top