



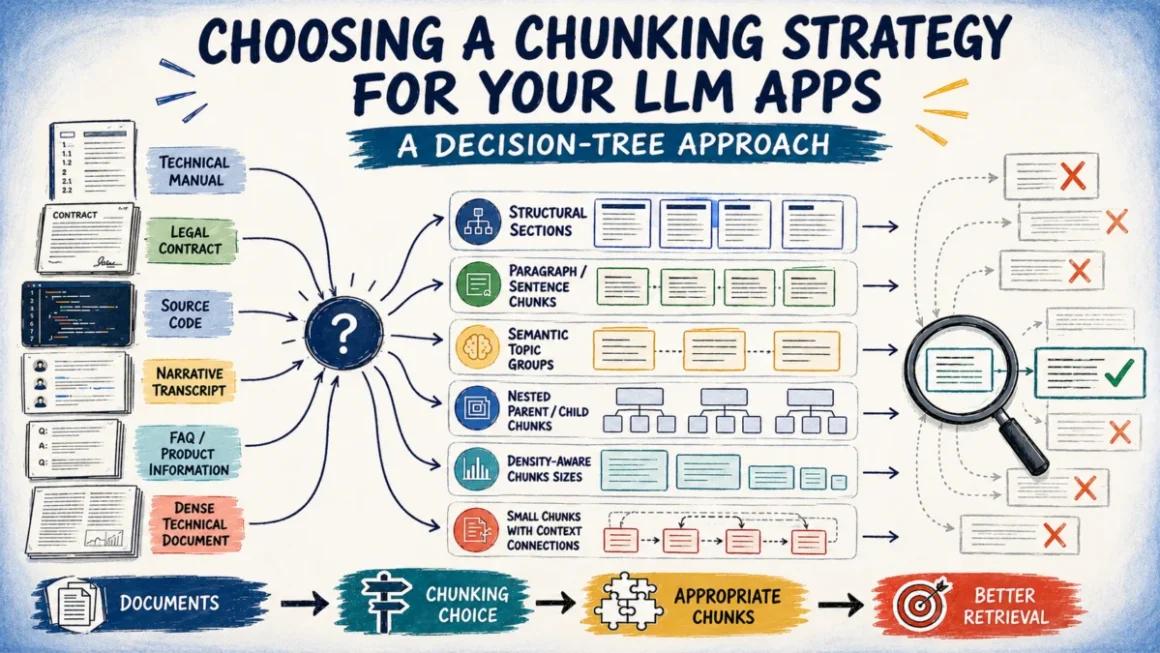
In the rapidly evolving landscape of Retrieval-Augmented Generation (RAG), the efficacy of an AI system is often determined long before the first prompt is sent to an LLM. While developers often obsess over model selection or fine-tuning, a critical bottleneck frequently lies in the preprocessing phase: chunking. As organizations move from experimental prototypes to production-grade […]
Headline
Tag: methodology
Back To Top