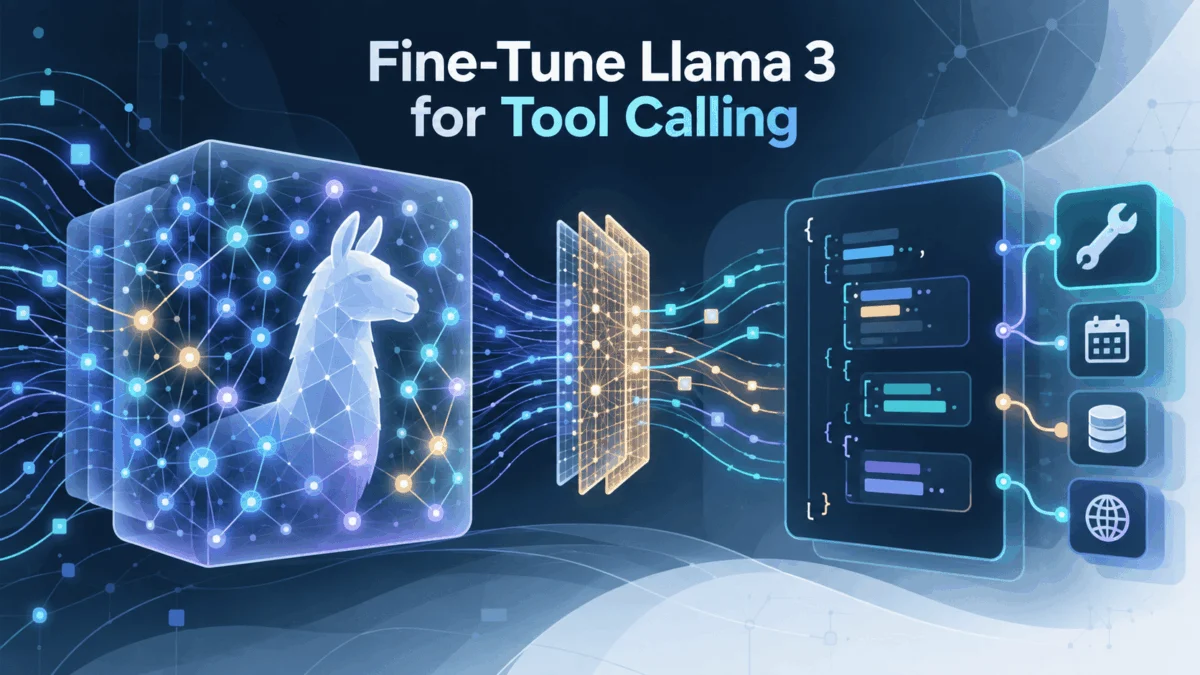
In the rapidly evolving landscape of Large Language Models (LLMs), the transition from "chatbot" to "autonomous agent" is defined by a single, critical capability: the ability to reliably invoke external tools. While models like Meta’s Llama 3 8B are exceptionally capable generalists, they often struggle with the "last mile" of reliability—consistently outputting valid, structured JSON payloads required by specific API schemas.
Prompt engineering can guide a model toward a desired format, but it remains non-deterministic. In a production environment, a single malformed response—a missing comma, a conversational filler, or an hallucinated field—can shatter an entire agentic pipeline. For developers, the solution lies not in more complex prompting, but in weight-level behavioral adjustment: fine-tuning.
This article explores the professional workflow for fine-tuning Llama 3 8B using Unsloth and QLoRA to achieve deterministic, schema-compliant tool calling.
The Core Challenge: Why Prompt Engineering Fails
To understand the necessity of fine-tuning, one must first recognize the inherent volatility of base LLMs. When prompted to return a JSON object, a base model may comply 90% of the time. However, under the pressure of ambiguous user queries or long-form conversational context, the model’s adherence to rigid syntax often degrades.
The model may append conversational prose ("Sure! Here is the JSON for your request…") or deviate from the required key names. In an agentic architecture, where the output is directly passed to a backend function or API, this "drift" is catastrophic.
Fine-Tuning vs. RAG
It is vital to distinguish between Retrieval-Augmented Generation (RAG) and fine-tuning. RAG is designed to provide the model with external facts—it expands the model’s knowledge base. Fine-tuning, conversely, is designed to adjust the model’s behavior. When you need a model to follow a strict output schema, adopt a specific persona, or execute a recurring functional pattern, fine-tuning is the industry-standard approach. By utilizing QLoRA (Quantized Low-Rank Adaptation), developers can achieve these deep behavioral modifications on consumer-grade hardware, such as the free tier of Google Colab’s T4 GPU.
Chronology of the Implementation Pipeline
The process of creating a specialized tool-calling agent follows a disciplined sequence: environment configuration, dataset architecture, parameter-efficient training, and validation.
1. Environment Setup
The foundation of this project is the Unsloth library, which optimizes the memory footprint and training speed of Llama 3. By leveraging 4-bit quantization, we reduce the memory overhead of the 8B parameter model, making it viable for constrained environments.
!pip install "unsloth[colab-new] @ git+https://github.com/unslothai/unsloth.git"
!pip install --no-deps xformers trl peft accelerate bitsandbytes
Once installed, verifying the CUDA environment is mandatory to ensure the T4 GPU is correctly mapped. This setup allows for the loading of the pre-quantized unsloth/llama-3-8b-Instruct-bnb-4bit model, which eliminates the need for massive downloads and complex Hugging Face authentication tokens.
2. Attaching LoRA Adapters
Rather than retraining the entire model, we inject trainable matrices into the attention layers. This process, known as LoRA, focuses the learning on roughly 1% of the total model parameters.
Key technical considerations include:
- Rank (r): A value of 8 is generally sufficient for behavioral tasks. Increasing this value adds capacity but risks overfitting on small datasets.
- Target Modules: We specifically target
q_proj,k_proj,v_proj,o_proj,gate_proj,up_proj, anddown_projto ensure comprehensive adaptation. - Dropout: Setting
lora_dropout=0is critical for Unsloth’s optimized training kernels.
3. Dataset Engineering: The Foundation of Reliability
The quality of the fine-tuned model is entirely dependent on the quality of the training data. For tool calling, each training example must contain:
- System Prompt: A rigid declaration of available tools and their JSON structure.
- User Query: A natural language input that maps to a specific tool.
- Target Output: The exact, error-free JSON payload expected.
In production, professional practitioners avoid "noisy" data. A dataset of 200 high-quality, diverse examples covering edge cases—such as multi-argument tools or queries that require clarification—will significantly outperform a larger, uncurated dataset.
Supporting Data and Technical Nuances
When preparing the data, using tokenizer.apply_chat_template() is non-negotiable. Llama 3 has a specific internal format for chat interactions. Manually constructing these strings risks breaking the model’s tokenization logic. By using the standard chat template, you ensure that the model understands the role-based separation between the system, user, and assistant.
Monitoring Training Loss
During the SFTTrainer phase, tracking the training loss is the primary diagnostic tool.
- Healthy Range: A gradual decline toward 0.1–0.3.
- Overfitting Indicator: If the loss hits near-zero too quickly, the model is likely memorizing the training examples rather than learning the generalized logic of JSON structuring.
If this occurs, the developer must either increase the dataset size or introduce synthetic variations of the existing training queries.
Implications for Agentic Frameworks
The implications of successfully fine-tuning a model for tool calling are profound. Once a model is "locked" into a specific JSON format, it becomes a predictable component of a larger system.
Integration with LangChain and LlamaIndex
Once the model is fine-tuned and the LoRA adapters are saved, this "Tool Caller" can be integrated into mature frameworks like LangChain or LlamaIndex. These frameworks act as the "orchestrator," while your fine-tuned Llama 3 acts as the "brain" that routes intent.
For example, when a user asks, "What is the stock price of Tesla?", the model no longer rambles. It outputs:
"name": "fetch_stock_price", "arguments": "ticker": "TSLA"
This output is then programmatically parsed by your application, which executes the corresponding API call. This eliminates the "LLM-in-the-loop" bottleneck where developers previously had to write complex regex parsers to salvage JSON from chatty, unpredictable model outputs.
Official Recommendations and Best Practices
As outlined by practitioners at Machine Learning Mastery, the transition to specialized models requires a shift in mindset from "general knowledge" to "operational logic."
- Iterative Testing: Always reserve a holdout set of queries that the model has never seen during training to validate that it has learned the logic of tool calling rather than simply memorizing training pairs.
- Temperature Control: During inference, maintain a low temperature (e.g., 0.1). High creativity is the enemy of structured data; you want the model to be as deterministic as possible.
- Schema Enforcement: Even with a fine-tuned model, it is recommended to pair the output with a lightweight validator (such as Pydantic) to ensure the generated JSON strictly adheres to your API schema before execution.
Conclusion
Fine-tuning Llama 3 8B for custom tool calling represents a turning point for developers looking to move beyond prototype-grade agents. By utilizing the Unsloth framework and QLoRA, teams can bypass the prohibitive costs and hardware requirements of full-scale training while achieving high-fidelity, deterministic performance.
The process—from installing dependencies to the final validation of JSON output—takes less than an hour, but the result is a robust, scalable architecture capable of bridging the gap between human intent and machine execution. As we look toward the future of AI, the ability to "program" the behavioral constraints of an LLM through targeted fine-tuning will remain a foundational skill for any serious machine learning engineer.