










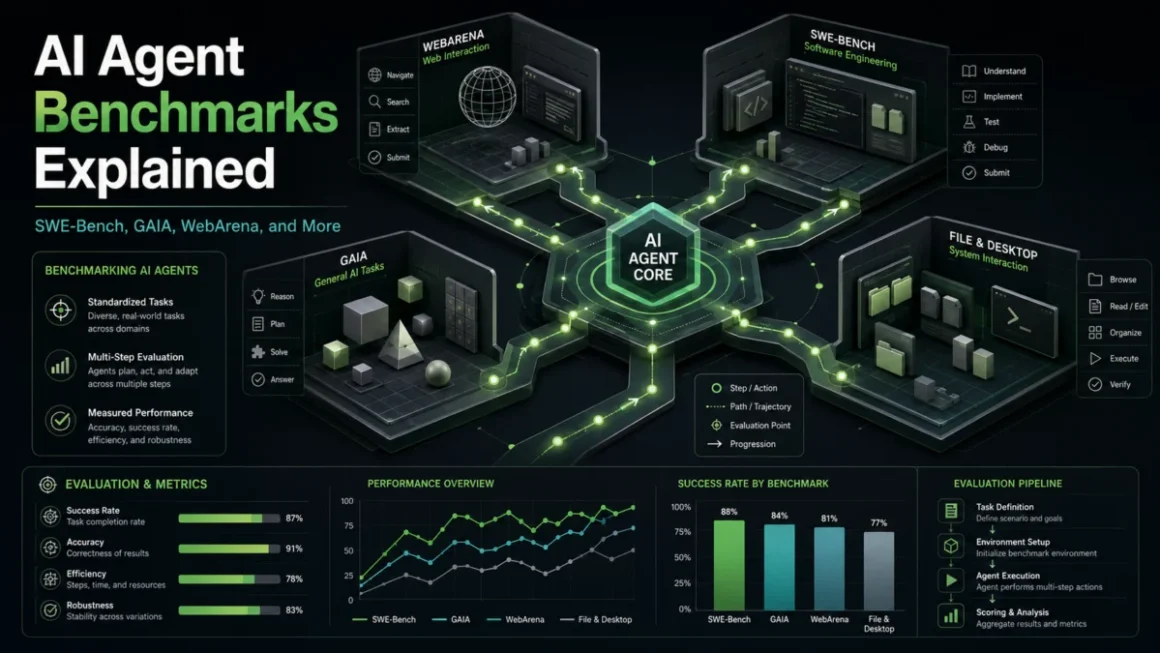
In the current landscape of artificial intelligence, a fierce arms race is underway. Every major AI laboratory and independent provider claims their latest agent architecture is "state-of-the-art." Weekly, new leaderboards emerge, and marketing departments fill social media feeds with glowing bar charts and soaring percentage points. Yet, for the enterprise engineer or the product manager […]
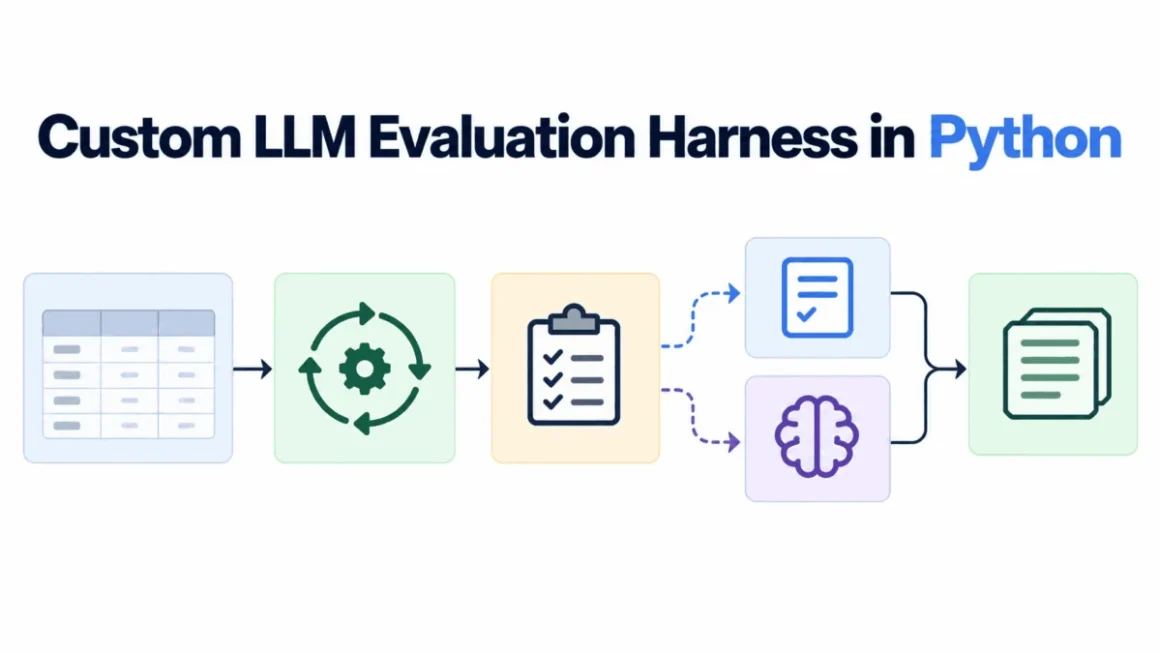
Beyond Benchmarks: Building a Custom LLM Evaluation Harness from Scratch
In the rapidly evolving ecosystem of Generative AI, public benchmarks like MMLU, GSM8K, and HumanEval serve as essential barometers for general model intelligence. However, for organizations deploying Large Language Models (LLMs) into production, these generic scores are often insufficient. They fail to account for the nuances of specific business logic, safety constraints, and domain-specific RAG […]
The Mirage of Accuracy: Why AI Hallucination Benchmarks Are Failing Enterprise Reality
In the competitive race to dominate the artificial intelligence landscape, model release pages have become increasingly standardized. Developers boast of "low hallucination scores"—often citing figures under 1% on industry-standard factual accuracy tests. To the casual observer or a prospective enterprise buyer, these numbers suggest that the era of AI error is drawing to a close. […]