










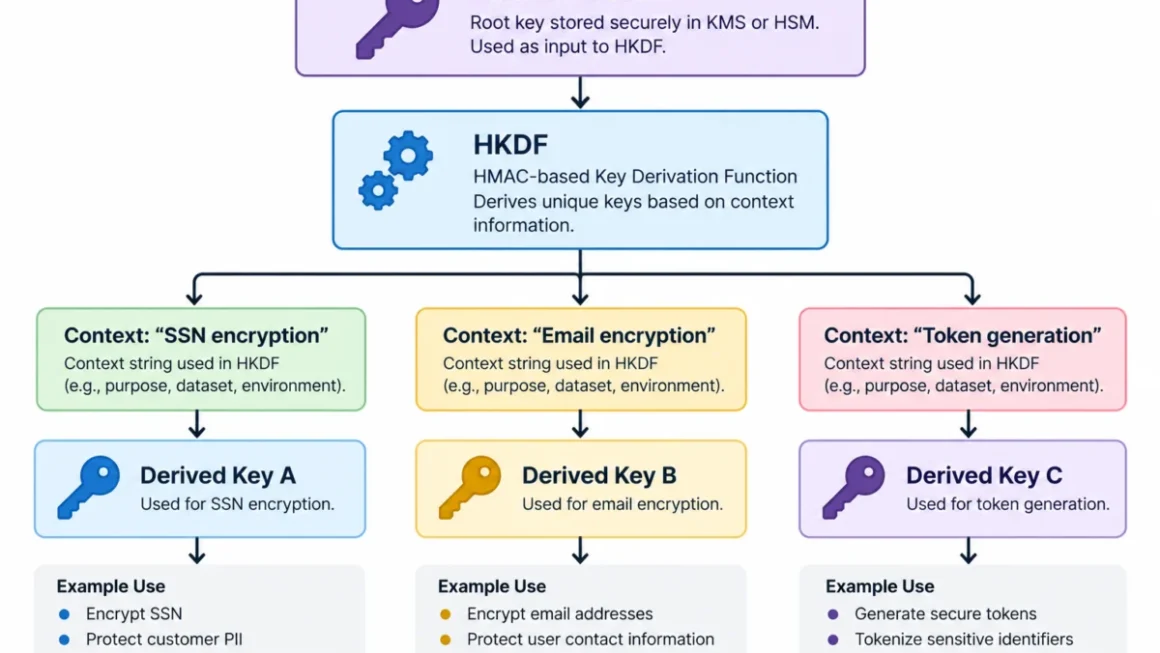
SAN FRANCISCO — In the modern enterprise data landscape, engineering teams face a perpetual balancing act: the mandate to protect sensitive customer information versus the operational necessity of leveraging data for business intelligence. Nowhere is this tension more pronounced than in the architecture of massive data pipelines processing Personally Identifiable Information (PII), such as Social […]
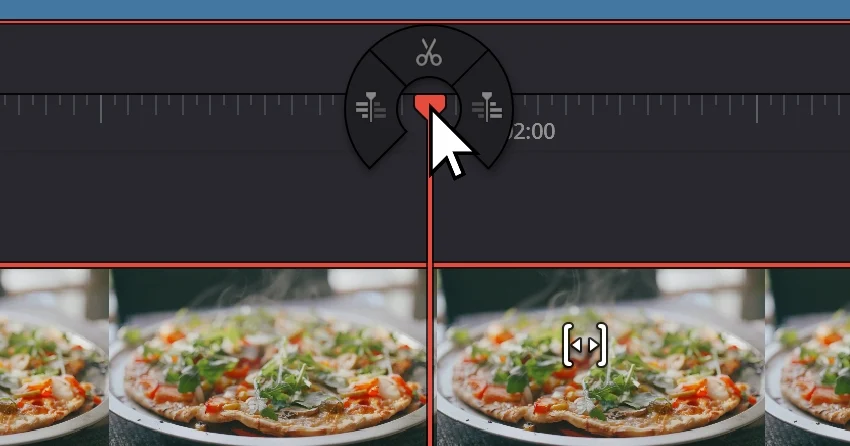
Masterclass: How to Add and Insert Video Clips in DaVinci Resolve Without Breaking Your Timeline
Post-Production Deep Dive: Professional video editing relies on precision, and few pieces of software demand—or reward—precision quite like DaVinci Resolve. Whether you are assembling a quick social media clip or color-grading a cinematic feature, mastering timeline architecture is essential. Here is a comprehensive guide to inserting and adding video clips cleanly, keeping your edits synced, […]
Beyond the Monolith: Why Cloudflare’s EmDash CMS is Redefining the Jamstack Without Dethroning WordPress
By WPDirecto Editorial Desk Published in partnership with insights from xCloud, Cloudflare, Patchstack, and W3Techs. Main Facts: The Current Landscape of Content Management Six months after its initial unveiling and following the official release of version 1.0, EmDash—the open-source Content Management System spearheaded by Cloudflare—has firmly established itself as a formidable alternative to WordPress. However, […]
The Silent Crisis: Why Your Brand’s AI Reputation is Being Built Without You
The rapid integration of Large Language Models (LLMs) into search engines has fundamentally altered the digital landscape. For years, businesses optimized their local SEO strategies to rank in the "local 3-pack" or appear on the first page of traditional search results. Today, that paradigm is shifting. Instead of presenting a curated list of links, AI […]
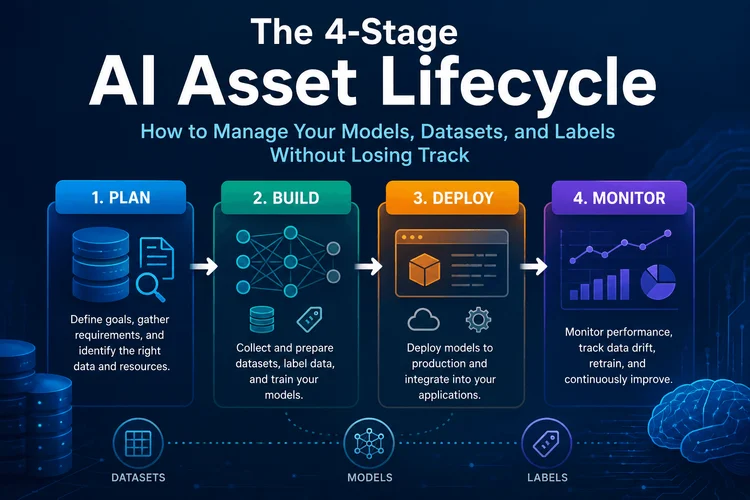
The 4-Stage AI Asset Lifecycle: How to Manage Your Models, Datasets, and Labels Without Losing Track
TL;DR Every machine learning project produces three core assets: labeled datasets, trained models, and the schemas that define how labels are structured. Most teams manage code with Git, infrastructure with Terraform, and models with… nothing systematic. The result is duplicated work, untraceable training data, models in production that nobody can reproduce, and compliance gaps that […]