










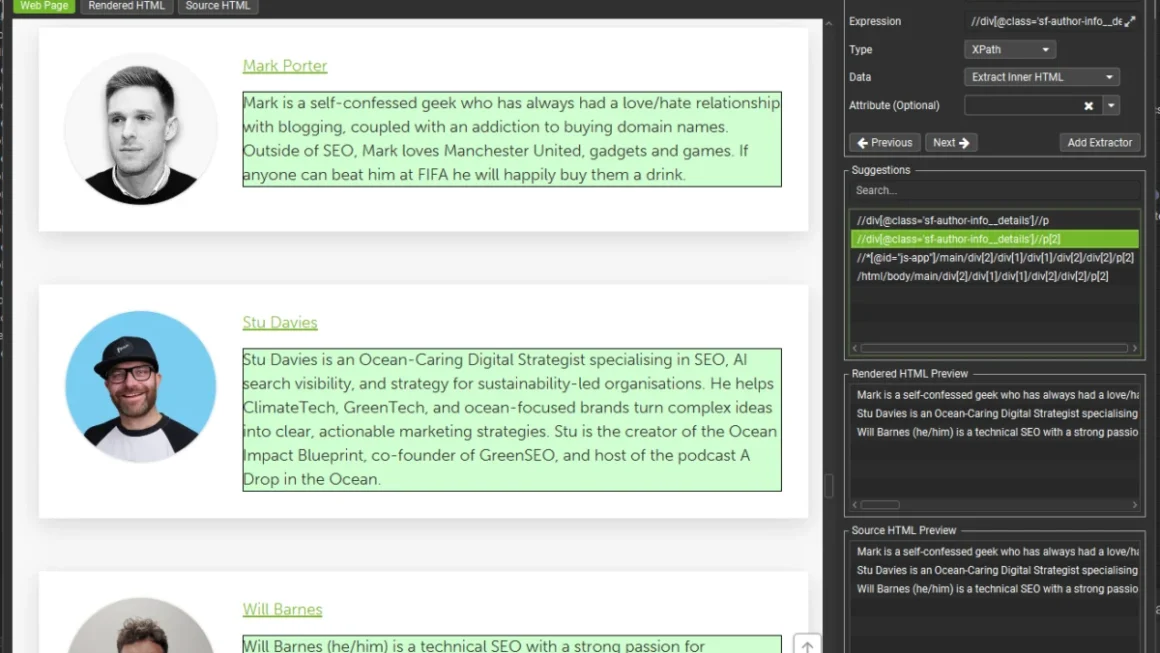
As artificial intelligence and Large Language Models (LLMs) cement their place in modern technical operations, search engine optimization (SEO) professionals and data engineers face a growing operational hurdle. Building Retrieval-Augmented Generation (RAG) pipelines, preparing fine-tuning datasets, and executing large-scale content audits all begin with the same fundamental requirement: extracting unstructured web content and transforming it […]
Beyond the Markdown Mirror: Why AI Agents Need Actions, Not Just Text, to Fix the Web
By Tech & Digital Infrastructure Desk Published in collaboration with No Hacks Main Facts The evolution of the web is currently suffering from a severe misdiagnosis. While publishers and developers rush to adopt "markdown mirrors"—text-only versions of websites tailored for Large Language Models (LLMs)—they are solving the wrong half of the problem. Serving markdown to […]
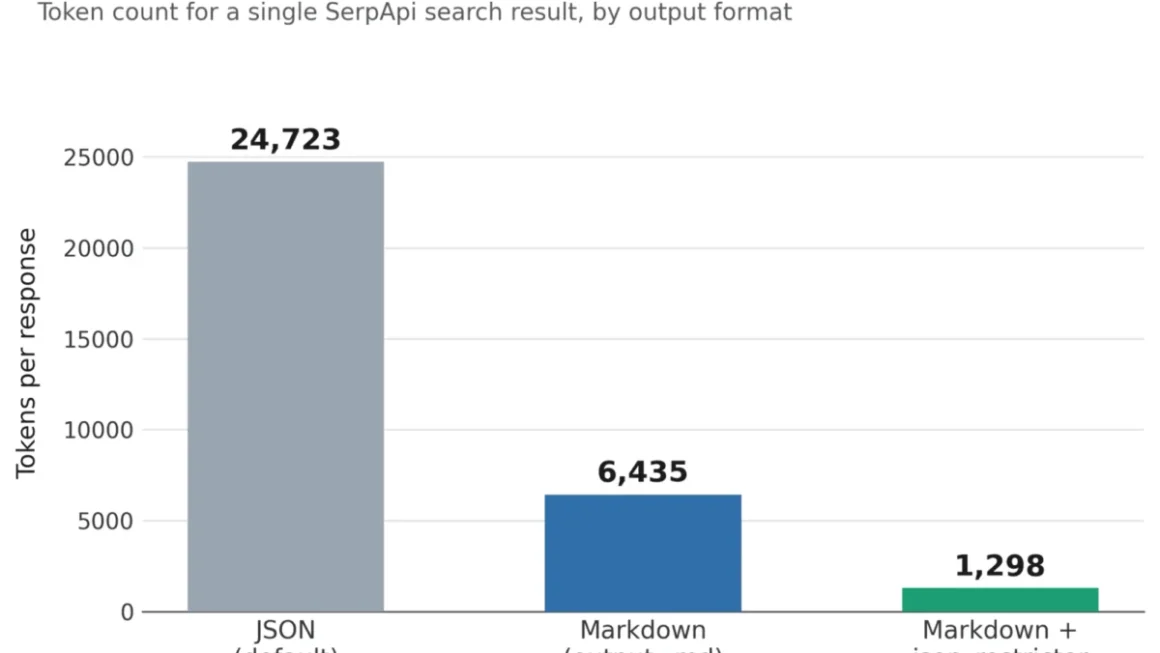
The Token Tax: How Data Formatting is Draining AI Budgets and How Markdown is Changing the Game
In the rapidly evolving landscape of Large Language Model (LLM) integration, developers are hitting an unexpected wall: the "Token Tax." As AI agents become more autonomous, their tendency to ingest massive volumes of search results, file retrievals, and log data has turned context windows into a premium resource. Every token consumed is a direct hit […]