In the rapidly evolving landscape of Large Language Models (LLMs), Retrieval-Augmented Generation (RAG) has emerged as the gold standard for grounding AI in private, proprietary data. However, standard RAG architectures suffer from a fundamental "blind spot": they are primarily text-centric. When presented with a PDF containing embedded charts, intricate architectural diagrams, or dense financial tables, these pipelines frequently falter. Text-based chunking processes often destroy table formatting and ignore images entirely, resulting in an incomplete, and often misleading, interpretation of the source material.
To bridge this gap, developers are turning to multi-modal RAG pipelines—systems designed to treat images as first-class, retrievable citizens alongside text. By integrating the visual context of a document with its narrative prose, organizations can finally extract meaningful insights from complex, media-rich files. This guide explores the engineering architecture behind building a robust, multi-modal RAG system using Python, LangChain, Unstructured, and OpenAI’s GPT-4o.
Main Facts: The Multi-Modal Shift
The core challenge in modern document processing is "context fragmentation." When a document is flattened into plain text, the relationship between a chart and the analysis surrounding it is lost. A multi-modal RAG system solves this by creating a unified retrieval space.
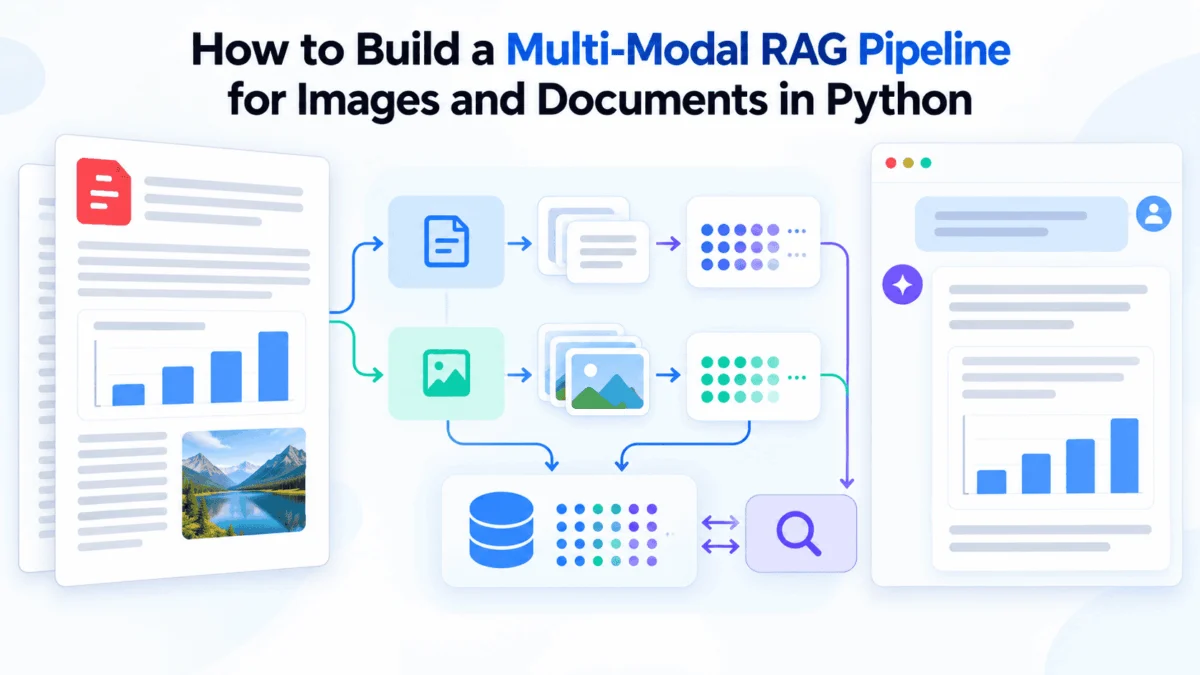
The system functions on a four-stage lifecycle:
- Parsing: Deconstructing the document into discrete elements—paragraphs, tables, and image files.
- Summarization: Converting visual data into descriptive, searchable text via vision-capable LLMs.
- Vectorization: Storing both text chunks and image summaries in a high-dimensional vector space.
- Synthesis: Executing a query that retrieves both visual and textual evidence, feeding them into a multi-modal model like GPT-4o for a cohesive response.
Unlike local, hardware-intensive models, this API-driven approach ensures scalability, making it ideal for enterprise-grade applications such as financial reporting, medical imaging analysis, and legal document discovery.
Chronology of Development: From Parsing to Synthesis
The development of a multi-modal pipeline requires a structured approach to data handling.
Phase 1: Intelligent Parsing
Using the unstructured library, developers can partition a PDF not as a string of characters, but as a collection of semantic objects. By setting infer_table_structure=True and extract_image_block_types=["Image"], the pipeline isolates visual content, saving images into dedicated directories while preserving text blocks.
Phase 2: Generating "Visual Proxies"
Vector databases operate on text embeddings. To make an image "searchable," the pipeline must generate a natural language summary that captures the essence of the visual. By passing images through GPT-4o, the system creates a textual proxy—a detailed description of the chart or diagram. This summary is then embedded and stored, serving as the "search handle" for the raw image.
Phase 3: The Multi-Vector Store
Standard retrievers struggle when one query could map to two different data formats. A MultiVectorRetriever is essential here. It manages two distinct stores: a vector store for similarity search (where the embeddings of text and image-summaries live) and a document store (the "source of truth") where the actual text and original images reside.
Phase 4: Multimodal Retrieval and Generation
When a user asks, "What does the revenue chart show for Q3?", the retriever locates the most relevant image-summary embedding. The system then fetches the raw image file, encodes it into a Base64 string, and sends both the text context and the image data to GPT-4o, which provides an answer grounded in both modalities.
Supporting Data: Why Multi-Modal Matters
The necessity of this approach is backed by the current architecture of modern AI. According to recent research from KDnuggets, AI systems are increasingly moving toward native multi-modal reasoning.
Consider the limitations of traditional chunking:
- Table Data: When a table is converted to raw text, column-to-row relationships are often obscured, leading to a 30-40% drop in retrieval accuracy for numerical queries.
- Image Relevance: In technical manuals, the diagram is often more informative than the surrounding text. A system that ignores images effectively discards 50% or more of the document’s total information density.
By utilizing the MultiVectorRetriever, the system maintains a high-fidelity connection between the query and the visual, ensuring that when an image is retrieved, the model "sees" the same pixels the user is asking about.
Technical Implementation: Prerequisites
To begin, you will need an OpenAI API key and the necessary Python environment. The system relies on poppler-utils to handle PDF rendering, a critical dependency for the unstructured library.
Installation:
pip install langchain langchain-openai unstructured[pdf] chromadb pillow
apt-get install -y poppler-utils
Environment Setup:
import os
os.environ["OPENAI_API_KEY"] = "your-api-key-here"
The pipeline architecture emphasizes modularity. By keeping the docstore (the raw files) separate from the vectorstore (the searchable index), developers can optimize memory usage—storing large images on disk while keeping lightweight embeddings in memory.
Implications for Enterprise AI
The shift to multi-modal RAG has profound implications for how businesses manage their knowledge bases.
1. Improved Decision-Making
In sectors like finance and engineering, decisions are rarely based on prose alone. The ability to cross-reference a Q3 earnings spreadsheet (table) with a bar graph (image) and a CEO’s summary (text) within a single query provides a holistic view that was previously impossible.
2. Operational Efficiency
By automating the "reading" of diagrams and charts, companies can reduce the manual effort required to audit complex documents. This creates a "digital assistant" capable of navigating long-form documentation with human-like visual comprehension.
3. Future-Proofing
The current framework, while powerful, is only the beginning. As vision-language models (VLMs) become faster and cheaper, the "summary" phase may eventually be bypassed. Emerging models like ColPali are already demonstrating the ability to embed entire document pages as images, potentially rendering traditional parsing steps obsolete.
Conclusion
Building a multi-modal RAG pipeline is an exercise in bridging the gap between digital data formats. By treating images as first-class, searchable entities, developers can create systems that truly understand the context of complex documents. While the setup—involving parsing, summarization, and multi-vector storage—requires a higher level of engineering rigor than standard text RAG, the payoff is a significantly more capable, accurate, and insightful AI system.
As you refine your pipeline, consider implementing re-ranking algorithms to sharpen the precision of your retrievals, or explore persistent storage solutions like ChromaDB to ensure your system is production-ready. In the world of AI, the ability to "see" is just as important as the ability to "read."